On this page
Before and After Launch
On the night of September 21, I posted: I have a feeling Opus 5 got routed to a new model.
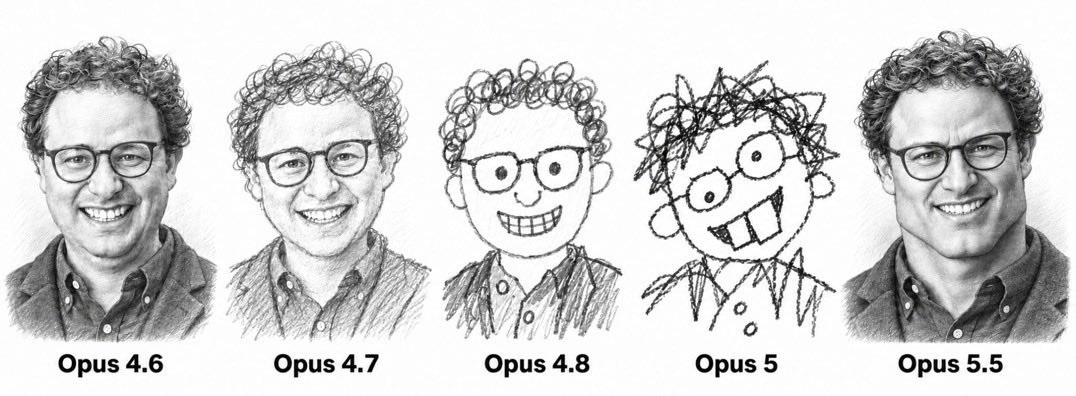
Why do I say that? Because holy shit, I could actually understand what it was saying!
A bit past 11pm the next night, I figured Opus 5.5 was probably dropping that night. Less than twenty minutes later: it’s live!
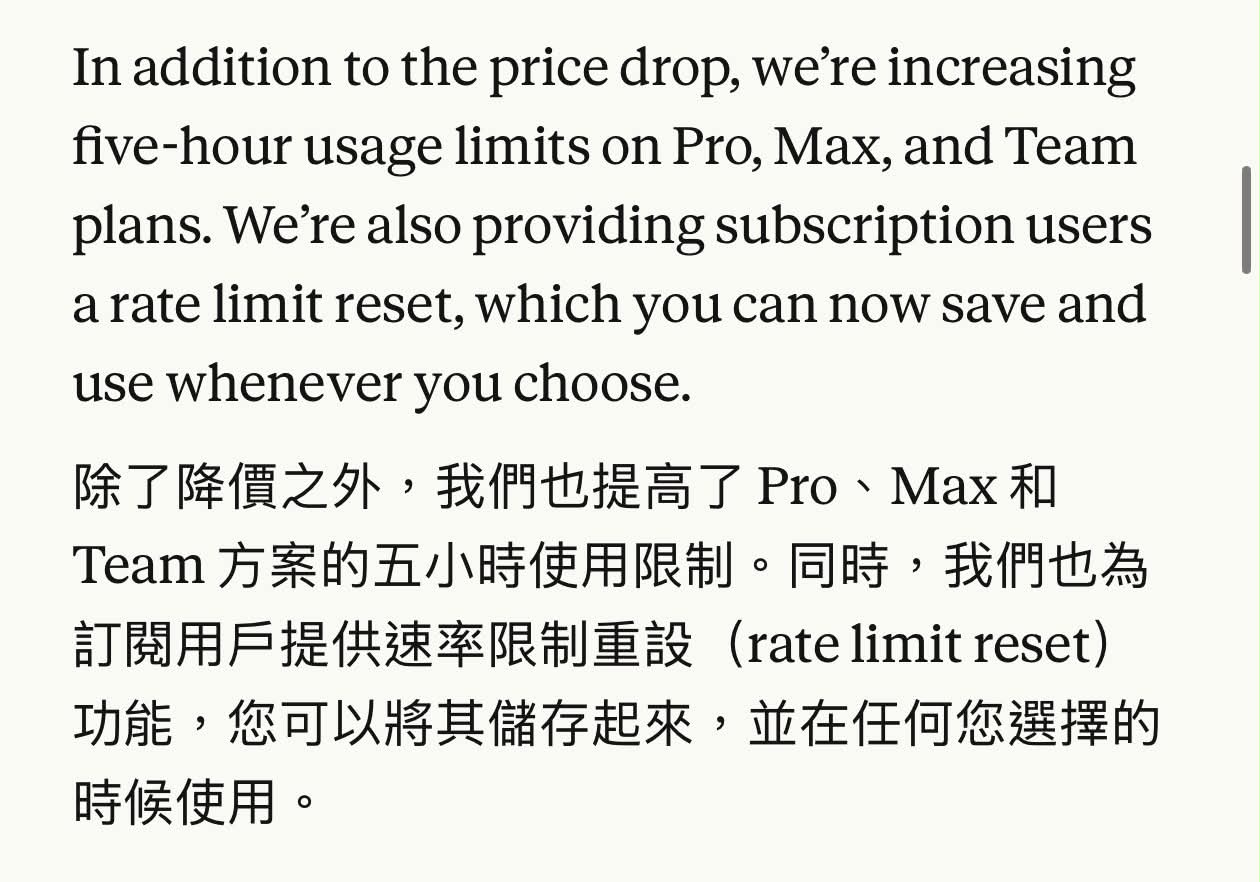
Half an hour after that, they gave us a reset card.
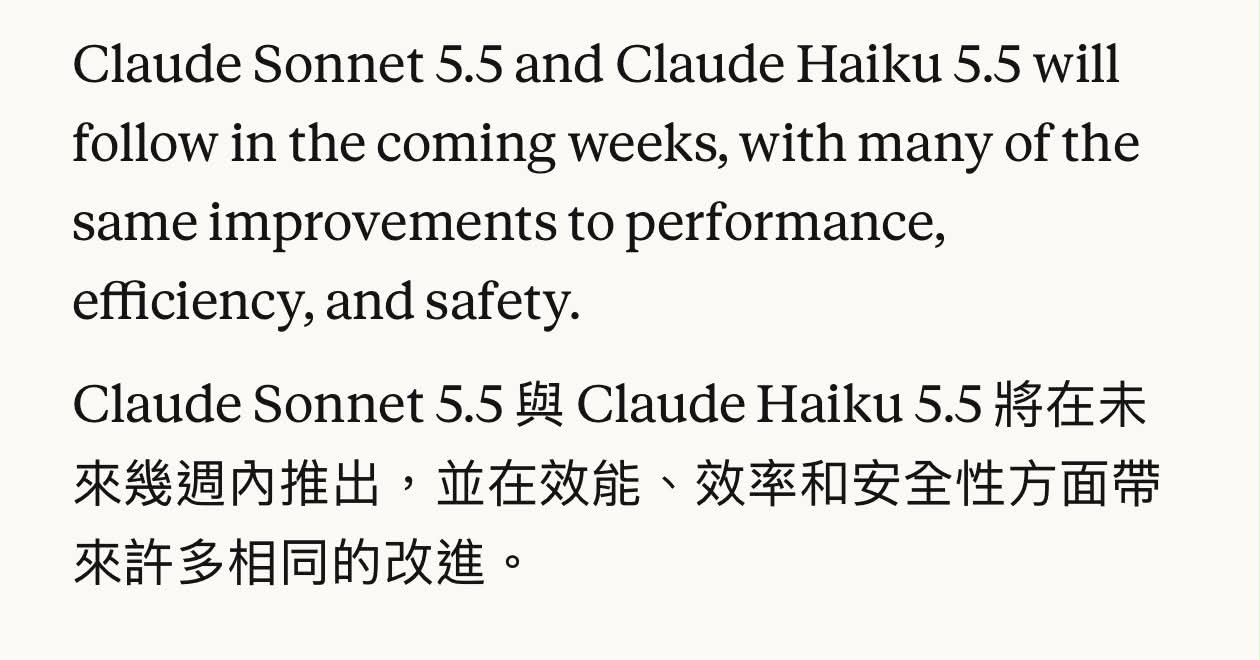
Both sides dropped new models the same night. Who wins the mindshare this time?
The Reddit Verdict
Twelve hours after launch-night madness, here’s a roundup of the harshest fathers in the model world: the Reddit crowd, and where the wind’s blowing right now.
Claude Opus 5.5:
- It finally talks like a person again, same as 4.6
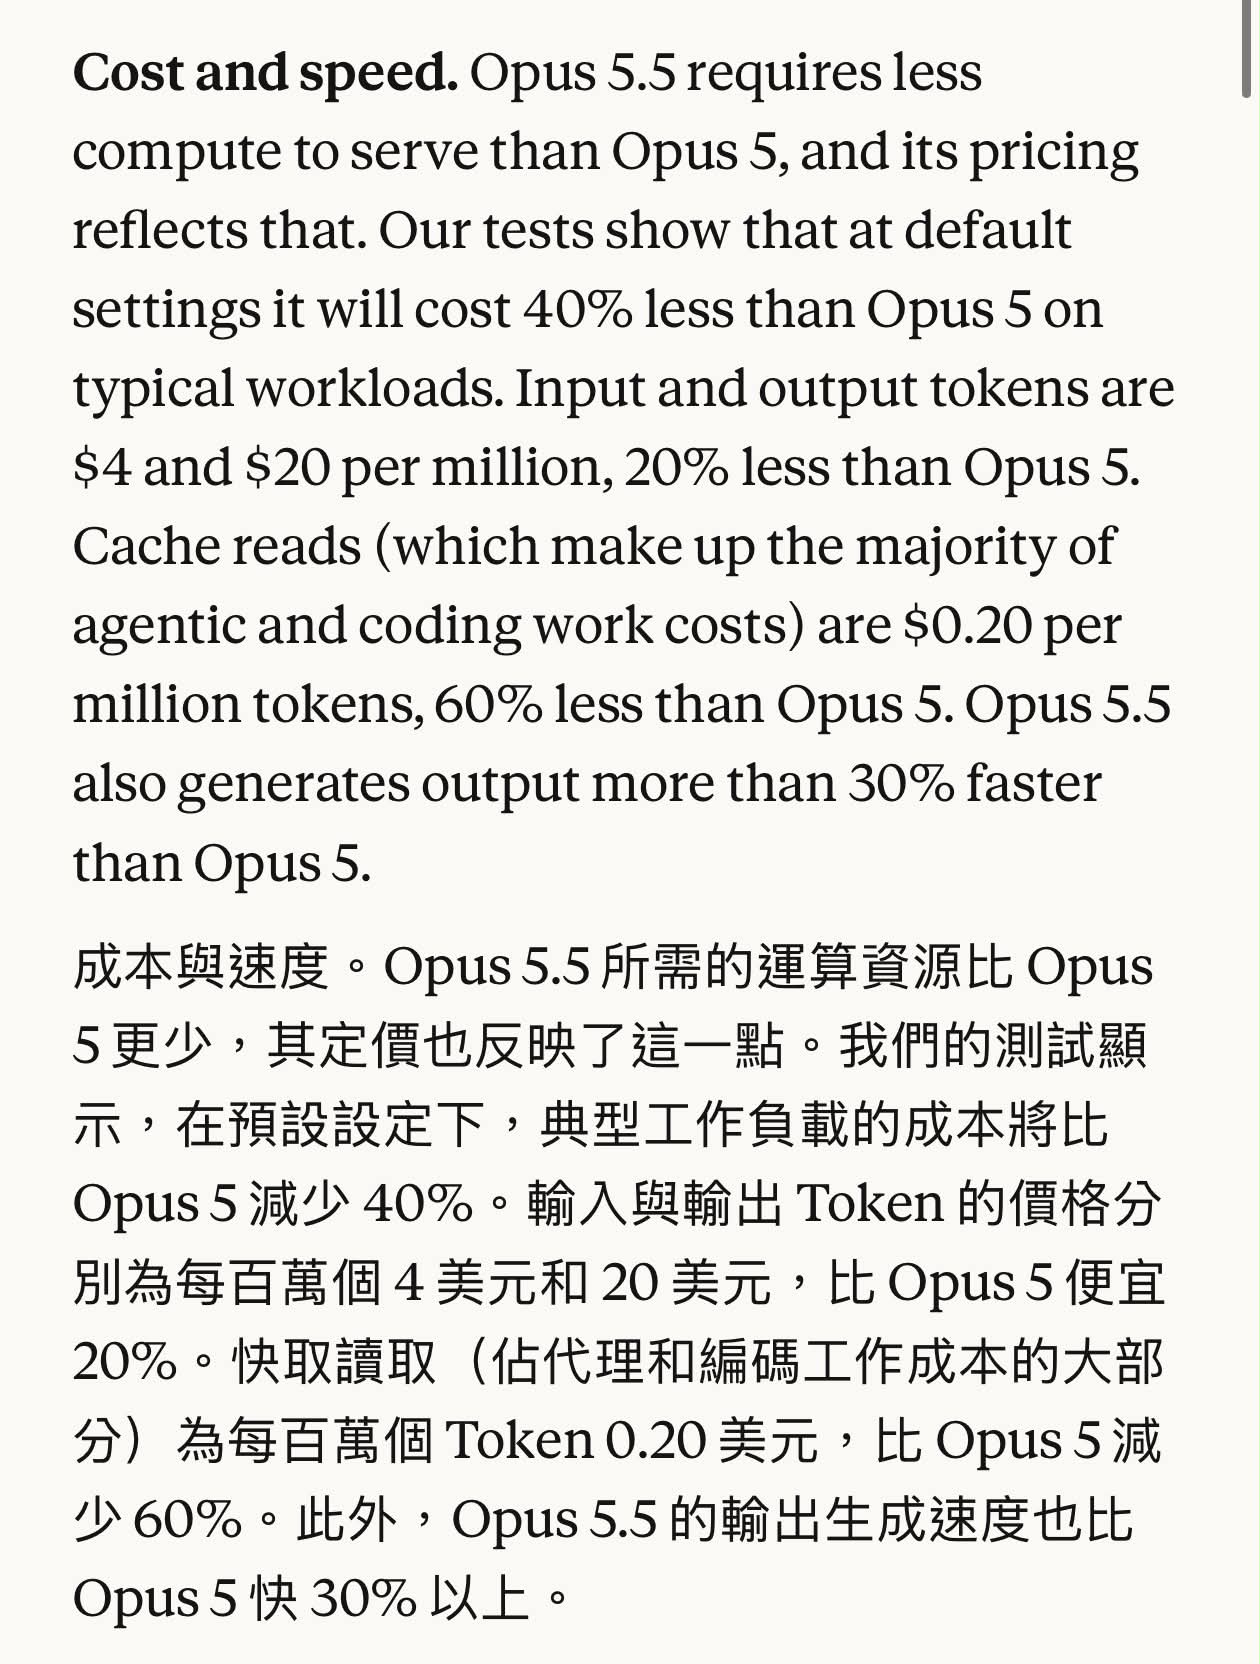
- Usage burn is down a lot (more efficient)
- Long tasks don’t drift as easily
- Wait, do I even still need Fable?
- Beats Astra on image generation
- Safety guardrails still overkill
- Will definitely get dumber in a few days
But overall the reviews are glowing. Looks like Anthropic’s fortunes might be turning around (?
GPT 6 Sol / Luna:
- Lower prices are always a win
- Sol 6 is basically just Terra with a new coat of paint
- Luna 6 is a serious downgrade in intelligence
- Sol 6 drops Skills sometimes (5.6 didn’t)
- Opus 5.5 planning + Sol 6 execution is the best combo
- What is the naming logic even at this point? Why change it again?
Overall people like the GPT price cut, but don’t think it counts as a real generational leap.
The original thread is here: https://www.reddit.com/r/OpenAI/comments/1wnxg0n/luna_6_is_a_massive_downgrade_over_luna_56_misses/
Opus 5.5 or Still Fable?
There’s the same discussion on Reddit (https://www.reddit.com/r/ClaudeCode/s/SZnTlgAogt), and the consensus is that Opus can’t replace Fable.
One person built the same feature separately with Opus 5.5 xhigh and Fable 5.1 high. Opus came out with “some seriously questionable architecture decisions,” while Fable nailed it in one pass. Their conclusion: hand Opus the tasks with a clear scope and a narrow context, and still go to Fable for the big projects.
Someone else said Opus tends to forget decisions it already reversed after about 15 turns of conversation, while Fable doesn’t do that in long conversations.
The common split is Fable as the lead, Opus running as a subagent for execution.
Fable’s biggest strength is architectural thinking and catching unknown unknowns. People outside are saying the same thing right now: Fable is still better at architecture than the latest Opus 5.5. So Opus is strong at implementation, but when it comes to the overall architecture, it tends to hand you something hard to follow.
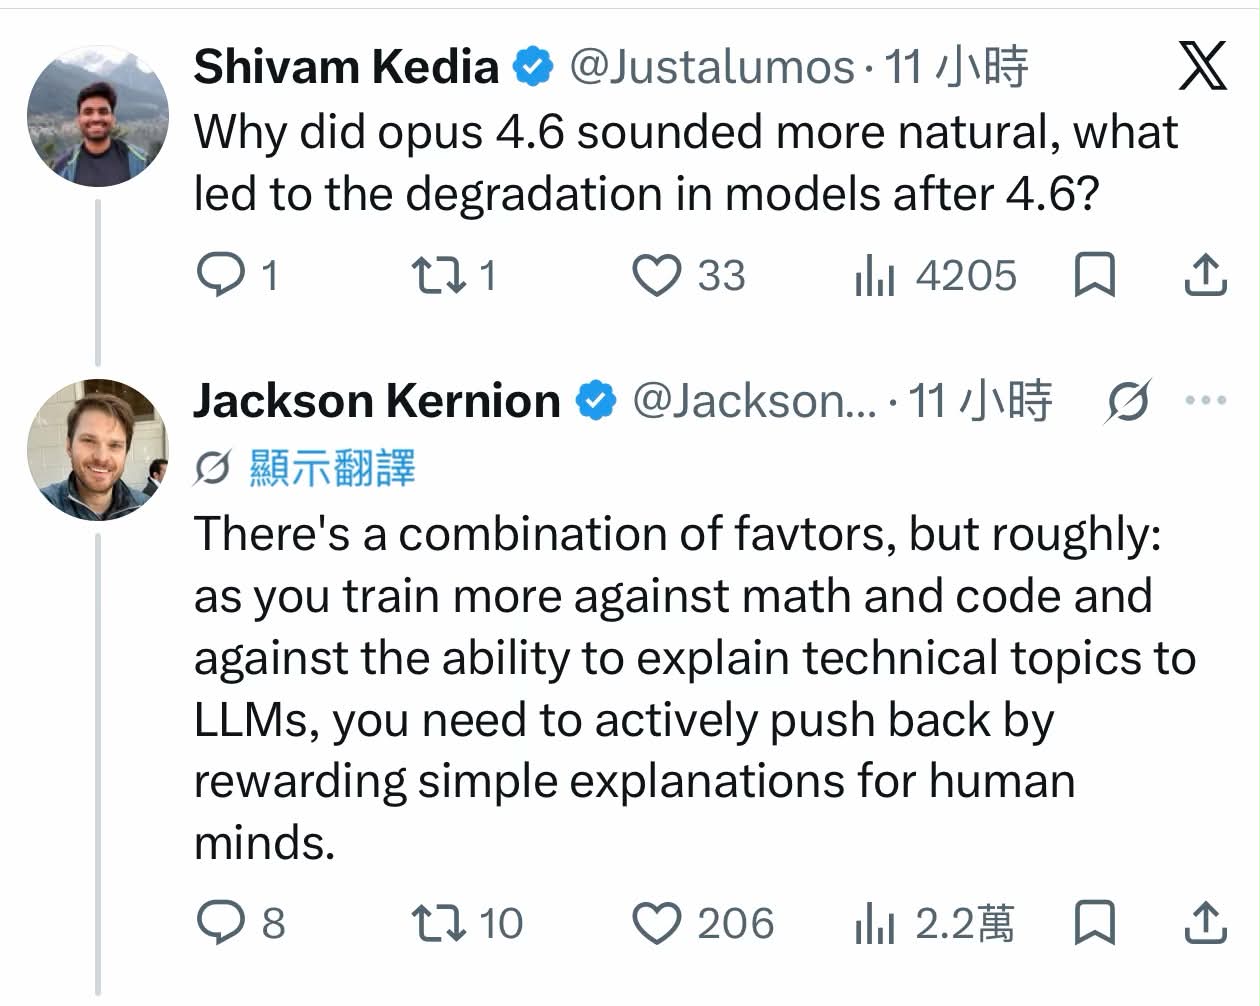
Why Opus Stopped Talking Like a Person After 4.6
Jackson Kernion, who works on model fine-tuning at Anthropic, answered why Opus versions after 4.6 often stop sounding like a person.
The short version: once training leans all the way into math and code, the model gets worse at talking (engineer-brain syndrome?). You have to actively reward “sounding more human” in training, or it doesn’t happen on its own.
I’m dying laughing.